Product Management, Engineering, User Experience
Product Experimentation
A systematic practice of testing business and product assumptions, learning from evidence, and deciding what to do next.
Product Experimentation at a glance
- Type
- Practice
- See also
- A/B TestingConciergeFake door testingCustomer InterviewA/B TestingAssumption MappingProduct DiscoveryValue Proposition
- Metrics
-
6 relevant metrics to track
- Observed behavior against the stated hypothesis and decision criterion
- Relevant audience, recruitment method and number of observations
- Revenue, delivery cost and customer outcomes for a paid pilot
- Primary outcome, guardrails and data quality for a controlled experiment
- Effect estimate and uncertainty, where supported by the study design
- Time from a decision question to usable evidence and a recorded next action
Product experimentation is a systematic practice of testing business and product assumptions, learning from evidence, and deciding what to do next. It applies both before launch, when the business idea is uncertain, and after launch, when a team wants to understand or improve an existing product.
The starting question is not “Which feature should we A/B test?” It is “What do we need to learn before making this decision?” Sometimes a controlled experiment is appropriate. Sometimes an interview, prototype, paid pilot or technical investigation is more useful.
Testing business ideas, experimentation and validation
These terms overlap, but they emphasize different parts of the work:
| Term | Useful question | What it emphasizes |
|---|---|---|
| Testing business ideas | Could this idea work for customers and the business? | Examining assumptions about desirability, feasibility and viability |
| Product experimentation | How will we generate evidence and learn from it? | A repeatable process linking questions, tests, interpretation and decisions |
| Product validation | What does the evidence support, and is it enough for the next commitment? | Assessing confidence in a proposed product and the remaining uncertainty |
| Product testing | What aspect of the product are we evaluating? | A context-dependent term that can include customer evaluations, usability, performance or QA |
In Testing Business Ideas, David J. Bland and Alexander Osterwalder describe experimentation as a way to investigate business assumptions, connected to the Business Model Canvas and value proposition design. Testing therefore includes questions about customers, delivery and money, not only interface quality.
Terminology varies. Teresa Torres distinguishes assumption tests from controlled experiments, while business-idea testing literature uses “experiments” more broadly. Here, experimentation names the overall learning practice. Describe each individual method precisely: an interview does not become a randomized experiment because it appears in an experimentation program.
A QA test can show that a checkout meets its requirements without showing that customers want the offer. A usability session can reveal difficulty completing a task without measuring willingness to pay. These are complementary sources of evidence, not interchangeable verdicts on the whole business.
Core concepts of product experimentation
An assumption is something that needs to hold for the idea to work. A testable hypothesis makes that belief specific enough to investigate. Include the audience, situation, expected behavior and the evidence that would challenge it.
Start with consequential assumptions for which evidence is weak. Assumptions Mapping helps a team make that choice visible. A value proposition or business model canvas can surface beliefs; filling in a canvas does not verify them.
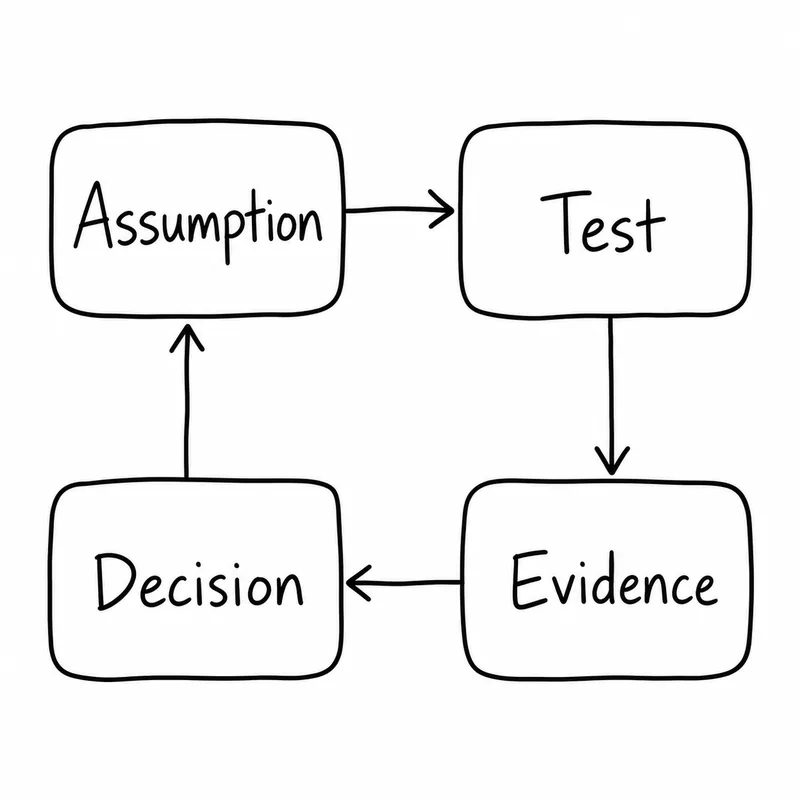
The decision might be to revise an offer, investigate a contradiction, test another assumption, stop an approach or make a limited investment. A positive result is not permission to skip the next important uncertainty.
Business and product assumptions to investigate
| Risk | Question | Example evidence to seek |
|---|---|---|
| Desirability | Does a particular audience face this problem and want the proposed outcome? | Recent behavior, current workarounds and responses to a concrete offer |
| Feasibility | Can we build and deliver the experience? | Technical investigations, service trials and operational constraints |
| Viability | Can the economics work? | Actual payment, delivery costs, acquisition costs and repeat demand |
| Usability | Can people complete the important task? | Observed task attempts using an appropriate prototype or product |
| Ethical risk | Could the idea or test cause unacceptable harm? | Review of affected people, data use and foreseeable consequences |
Strategyzer’s business-idea framing emphasizes desirability, feasibility and viability. Torres also explicitly considers usability and ethical assumptions. Use the categories as prompts to find overlooked risks, rather than spending the session debating labels.
Getting it right
Selecting the right experiment method
Choose a method for the uncertainty and decision, not simply for the lifecycle stage. A startup can run a randomized offer test when the design and audience support it; an established product team can still learn from a small prototype session.
| What you need to learn | Possible next method | Main limitation |
|---|---|---|
| How people currently handle a problem | Customer Interview, observation or existing service records | Accounts and observations do not isolate the effect of a proposed change |
| Whether people notice and express interest in an offer | Fake door testing | A click is not a purchase or evidence of repeat use |
| Whether people will pay and whether you can deliver value | A transparent paid Concierge pilot | Manual delivery may not scale; a recruited group may not represent the wider market |
| Whether someone can use the proposed interaction | Prototype testing with relevant tasks | Task success does not establish demand or business viability |
| Whether a change causes an outcome difference | A properly designed A/B test | Requires suitable assignment, measurement, sample and analysis |
Tell participants what the offer or pilot actually provides, handle payments and data responsibly, and avoid presenting unavailable functionality as an existing service. A test should not create a misleading promise you cannot fulfill.
Writing a strong hypothesis
Separate the belief from the test plan. “Independent shop owners will pay EUR 49 per month for a weekly stock report” is a belief about a particular offer. “Invite 20 eligible owners to a clearly described paid pilot and record paid starts” is one way to investigate it.
For a controlled experiment, specify the intervention, comparison, audience and outcome. For example, compare two onboarding flows on completing a useful first task, with errors and abandonment as guardrails. A predicted lift is a hypothesis to assess, not a result to promise.
Product experimentation process
Use this sequence at a scale appropriate to the decision:
- Name the decision. State what commitment the evidence should inform, who will decide and when.
- Choose the assumption. Identify the belief most likely to undermine the idea if it is wrong, considering both importance and existing evidence.
- Plan the evidence. Select a method, audience, recruitment approach, observations or metrics, and relevant safeguards. State the criterion for continuing, revising or stopping before seeing the results.
- Run and document the test. Keep a record of what was offered, to whom, under what conditions and what actually happened. Record deviations and missing data.
- Check the interpretation. Ask whether the evidence answers the hypothesis, what alternative explanations remain and how far the result can generalize.
- Decide and repeat. Record the next action, owner and unresolved risks. A limited next test can be more appropriate than either scaling or abandoning the whole idea.
Use the existing Experiment Sheet to make the plan explicit. The worked example below shows the reasoning without requiring a download or signup.
Worked example: paid interest without viable delivery
This scenario and every number in it are hypothetical. A team is considering a weekly stock-report service for independent shops at EUR 49 per shop per month. Before building integrations, it proposes a one-month paid pilot with manual preparation clearly disclosed.
The team identifies two assumptions and chooses its own preliminary decision criteria:
| Assumption | Planned check | Criterion set before the pilot |
|---|---|---|
| Enough eligible owners will pay for this offer to justify another test | Invite 20 owners with the relevant stock-management task; record actual paid starts | At least 5 paid starts within the offer period |
| The report can be delivered within a viable effort budget | Log preparation and support time during the pilot month | No more than 1 hour per shop per month at the assumed labor rate |
These are illustrative management thresholds, not statistical benchmarks or universal rules. The recruited owners are a small selected group, not a representative estimate of market demand.
Suppose four owners pay, and delivery takes two hours per shop during the month. At an assumed labor cost of EUR 30 per hour, that is EUR 60 in delivery cost against EUR 49 in revenue per shop, before acquisition, software and other expenses.
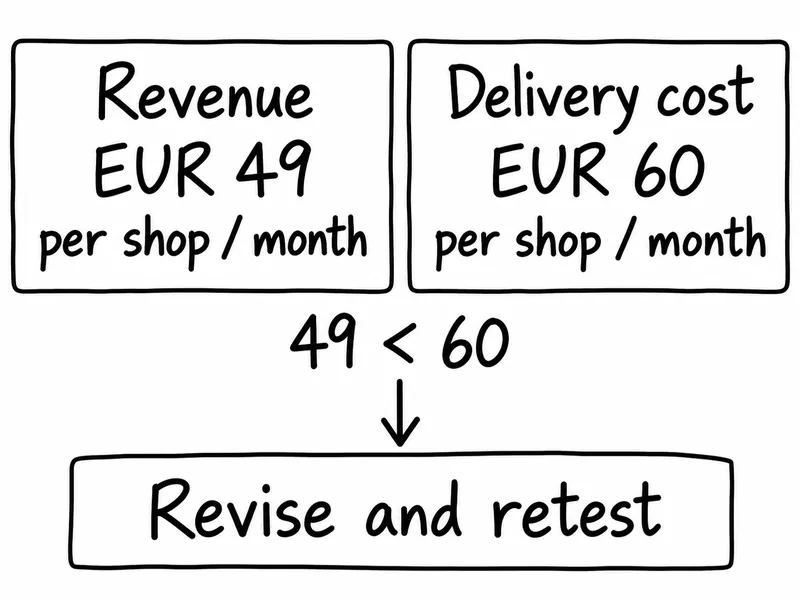
Neither preliminary criterion is met. The payments show that these four owners accepted this offer; they do not establish repeat demand, sustainable margins or a scalable delivery process. The team might narrow the report, investigate the costly steps and retest a revised offer before funding integrations. Automation could change delivery costs, but its cost and effectiveness are further assumptions to investigate.
The learning is more useful than labeling the business “validated” because somebody paid, or declaring there is no market because one pilot fell short.
Selecting metrics
Choose measures that match the question. For a paid pilot, record the offer, eligible invitations, payments, refunds, customer use and delivery effort. For a prototype session, retain task context, observed problems and uncertainty; do not turn a handful of sessions into a market-wide conversion forecast.
For controlled product experiments, distinguish:
- Primary outcome: the behavior or value relevant to the decision, such as reaching first value or completing a purchase.
- Guardrails: outcomes you should not materially worsen, such as errors, latency or abandonment.
- Diagnostics: measures that help explain behavior, such as clicks on an intermediate control.
- Data-quality checks: whether assignment, exposure and outcome records are reliable.
Microsoft’s pre-experiment guidance connects hypotheses, metrics, sample planning and randomization choices. A feature click can help diagnose a result, but it does not substitute for the intended customer or business outcome.
Interpreting results
First check whether the test ran as intended. Missing events, unexpected differences in group allocation or inconsistent exposure can make an apparent lift misleading. Microsoft’s during-experiment guidance highlights data quality, guardrails and the danger of interpreting repeatedly checked results without an appropriate analysis plan.
For a controlled comparison, inspect the estimated effect and its uncertainty alongside practical value and guardrails. Statistical significance does not establish that an effect is large enough to justify implementation. Conversely, an inconclusive result does not prove that variants are equivalent.
Do not lower the decision bar after seeing the result, cherry-pick a favorable segment or keep collecting data solely until a preferred answer appears. Treat unplanned segment findings as hypotheses for follow-up. Assess whether a short-term response might reflect novelty, and design longer observation where persistence matters.
For noncontrolled tests, explain the remaining alternatives. A successful pilot could depend on unusually attentive support, a favorable recruiting channel or early adopters. Follow-up research can investigate these explanations; it does not retroactively make the original test causal.
When to test, and when not to
Experimentation is relevant while searching for product-market fit. The appropriate activity may be a business-idea test rather than a live A/B experiment. Low traffic is a reason to reconsider the method, not to abandon learning.
Do not insist on an experiment for every decision. Existing evidence may already be sufficient for a small reversible change, and a known defect may simply need fixing. Pause a proposed test when it would expose people to unacceptable harm, cannot produce interpretable evidence or would cost more than the decision warrants. Choose another evidence source where practical.
Product experimentation tools and team habits
Start with the jobs the tools must do: capture the hypothesis and plan, recruit a relevant audience, present an offer or prototype, record observations, and share a decision. A document, spreadsheet and existing research tools may be enough for an early pilot.
Controlled production experiments additionally need reliable variant assignment, exposure and outcome instrumentation, suitable analysis and monitoring. Feature flags manage exposure; they do not automatically provide randomization or trustworthy inference. Buy or build infrastructure when the questions require it, rather than making a platform the prerequisite for all testing.
Building an experimentation culture
Review the question, method, evidence and decision together, including null, negative and inconclusive results. Keep records discoverable so the team can revisit assumptions when the audience, offer or product changes. Measure useful decisions and evidence quality alongside cycle time; experiment counts and win rates alone can reward low-value tests.
Choose the next testing playbook
The Validation Patterns overview helps you navigate the methods. Choose the next question:
| Decision question | Existing playbook |
|---|---|
| Is the customer problem worth addressing? | Validate the problem |
| Is there a reachable market for the offer? | Validate the market |
| Does the proposed experience solve the problem? | Validate the product |
| Will customers pay under realistic conditions? | Validate willingness to pay |
Use the glossary guide to understand the learning process, the playbooks to choose a direction and the individual plays to prepare a test. Keep the decision and remaining uncertainty visible throughout.
-
Can you experiment before product-market fit?
Hint Yes. Early experiments and assumption tests help investigate demand, willingness to pay, delivery and usability before committing to a product. You do not need a finished product or enough traffic for A/B testing. -
Are all assumption tests controlled experiments?
Hint No. An interview or prototype session can inform an assumption without isolating a causal effect. State what the method can establish rather than treating all tests as equivalent. -
How large a sample is needed?
Hint It depends on the question, audience, design and decision risk. A quantitative controlled test needs a sample plan based on its metric, baseline, detectable effect and statistical approach; a few qualitative sessions cannot estimate population demand. -
What is a minimum detectable effect?
Hint It is an effect size a statistical design is planned to detect at a specified power and error rate. Choose a design sensitive enough for the differences relevant to the decision; it is not a guarantee of the observed result. -
How long should an A/B test run, and when should it stop?
Hint Plan duration, sample and stopping rules before launch, accounting for the behavior cycle and analysis method. Monitor for harm and broken data, but do not declare a win merely because a repeatedly checked result crosses a threshold. -
What if a result is inconclusive?
Hint First check execution and data quality. If evidence is still insufficient, record that uncertainty and choose a justified follow-up. Do not lower the success criterion or keep extending the test simply to obtain a positive result. -
Do small teams need an experimentation platform?
Hint Not for every question. Interviews, manual pilots and prototypes can use simple records and existing tools. Controlled production experiments need reliable assignment, instrumentation, analysis and monitoring. -
Can several experiments run at the same time?
Hint Sometimes. Assess shared users, interacting changes and measurement dependencies. Record concurrent exposure and use appropriate assignment or exclusion designs where interactions could distort the result. -
How do feature flags, A/B tests and multivariate tests differ?
Hint A flag controls exposure but does not by itself create a valid experiment. An A/B test compares variants; a multivariate design studies combinations of factors and can examine interactions when its design and sample support that analysis. -
Does passing a test validate the whole business?
Hint No. Evidence supports a particular assumption in a particular setting. Interest, payment, repeat use, delivery capability and viable economics can require different checks.
You might also be interested in reading up on:
- Testing Business Ideas by David J. Bland and Alexander Osterwalder
- How to test your idea: start with the most critical hypotheses by Alex Osterwalder
- Assumption Testing: Everything You Need to Know to Get Started by Teresa Torres
- Patterns of Trustworthy Experimentation: Pre-Experiment Stage
- Patterns of Trustworthy Experimentation: During-Experiment Stage
Product Weekly · Curated by Anders Toxboe
Sign up for the Product Weekly newsletter.
Join 40,000+ product people who get a weekly selection of useful reads on building digital products, plus new Learning Loop resources and occasional product updates.
What will I receive?Takes 10 seconds. Free to subscribe, unsubscribe at any time. Privacy policy.